

1.1. Linguistic research perspectives
1.1.4. Linguistic perspectives to data science
So, what are the differences between how a data scientist and a corpus linguist work with textual data? As it turns out, there are several, which we will discuss throughout the course. Still, the most fundamental one is that (corpus) linguists are primarily interested in studying languages and discovering new things about them. At the same time, data scientists are typically interested in developing computational methods that allow us to do something with a specific set of texts, such as classify them into groups based on similar content or by pre-determined characteristics, weed out unwanted texts (such as spam emails), or present textual data using data visualisations. Consequently, while a linguist might be answering a question like when in history did English scientific texts begin to feature significantly greater frequencies of nominalisations or whether a particular suffix is equally productive in the various Englishes around the world, a data scientist might be engaged with monitoring live tweets to track discussions of a pandemic around the world, or creating a visualisation of how positive or negative newspaper portrayals of a particular politician have been over the last five years.
In addition to differences in the objectives, corpus linguists and data scientists working on text analysis also tend to differ in their training. Traditionally, corpus linguistic training did not include programming, and it is fair to say that advanced statistics are a relatively new addition to linguistic curricula at universities as well. Instead of programming, corpus linguists have primarily relied on corpus tools (see unit 1.4), which are computer software designed to analyse textual data and statistical software. By contrast, data scientists are often programmers capable of writing their software. However, they are often less knowledgeable about the theoretical aspects of languages and the many sociolinguistic, language historical and textual constraints that affect language.
One other field ought to be mentioned here: computational linguistics. In many respects, computational linguistics straddles the two fields of corpus linguistics and data science. Computational linguists are usually trained in linguistics, but they also receive a solid education in programming; in some ways, we could say that computational linguists are data scientists specialising in languages. Their work is typically done in fields such as machine translation, automatic annotation, speech recognition and other fields where computers are used to analyse and manipulate linguistic data.
The figure below gives an overview of the overlapping areas of activity and interest among the three fields.
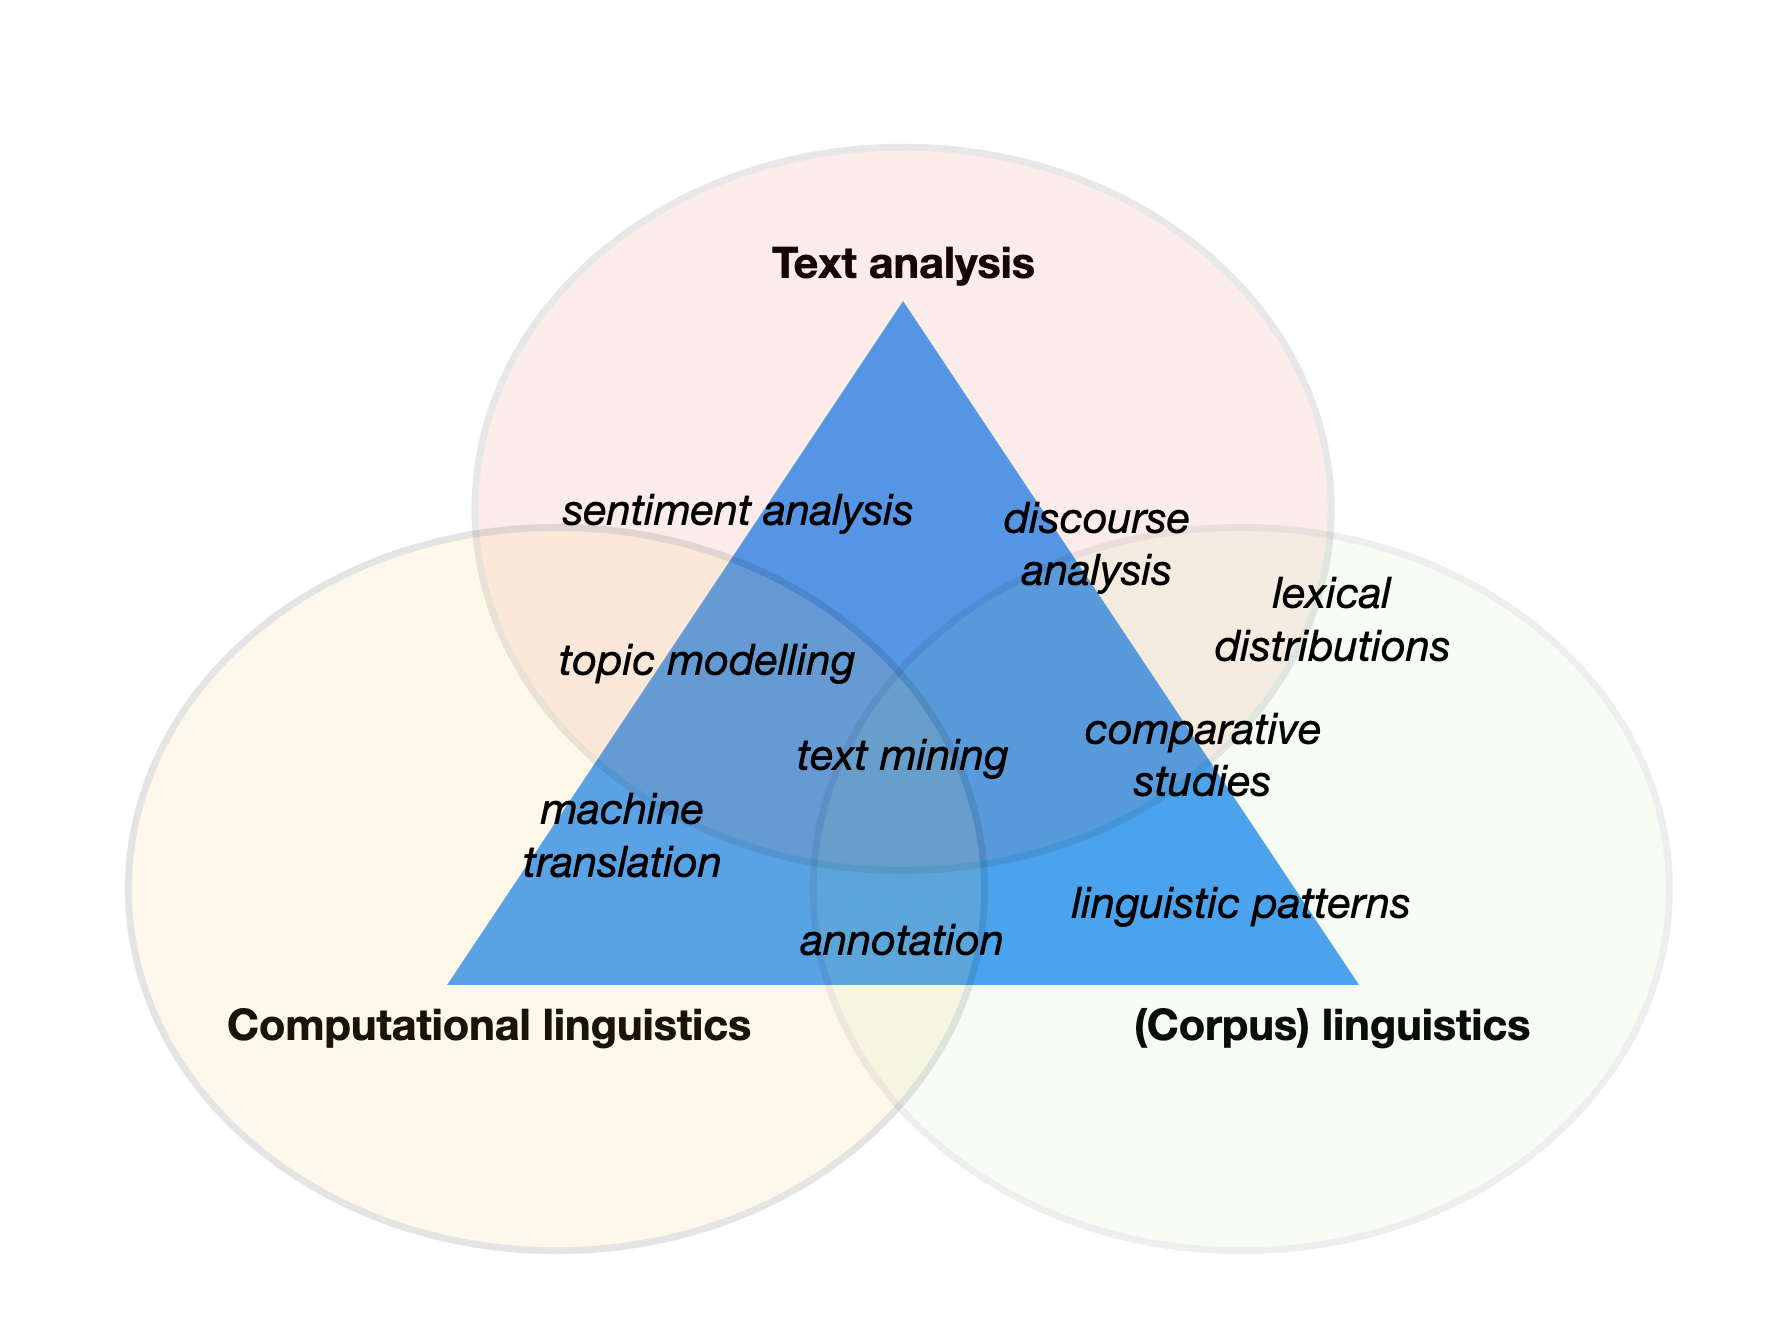
In recent years, there has been increasing collaboration between the different fields. Still, the fact that their disciplinary histories differ so markedly has meant plenty of work remains to be done before the potential synergies are realised. One of the objectives of this course is to bring these two fields together and explore what each field can give the other.