

3.1 How automatic methods work
3.1.2 Terminology
Before we get our hands dirty with how exactly automatic indexing is done, let us clarify these processes' important concepts and terms. There are a lot of different terms in the literature; we hope this lesson will provide some clarity.
According to the current ISO indexing standard (ISO 5963:1985, last reviewed and confirmed in 2020, International Organization for Standardization 1985), subject indexing performed by the information professional is defined as a process involving three steps:
-
Determining the subject content of a document;
-
A conceptual analysis to decide which aspects of the subject content should be represented; and,
-
Translation of those concepts or aspects into a controlled vocabulary or KOS.
Automatic subject indexing is then machine-based subject indexing where human intellectual processes involved in those three steps are replaced by, for example, techniques based on computational linguistics and statistics (more about these in the following lesson; see also "Text Analysis: Linguistic Meets Data Science" course).
In library science, the terminology of subject indexing involves several important concepts. Subject index terms may be derived either from the document itself, which is known as derived indexing (e.g., keywords taken from the title) or from KOS (see Units I and II) -- indexing languages that are formalized and specifically designed for describing the subject content of documents, which is known as assigned indexing or classification. In assigned indexing, index terms are taken from alphabetical indexing languages (using natural language terms with terminology control such as thesauri and subject headings); in classification, classes are taken from classification systems (using symbols, operating with concepts). The main purpose of assigned indexing using alphabetical indexing languages is to allow retrieval of a document from many different perspectives; typically, 3 to 20 elemental or moderately pre-combined subject terms are assigned. The main purpose of classification, assigning classes from classification schemes, is to group similar documents to allow browsing (of library shelves in the traditional environment and directory-style browsing in the online environment); typically, one highly pre-combined subject class is assigned. Similarly and as seen from the table below, when automated methods are used, they can be based on either assigned indexing, which is preferred because of all the benefits of assigning terms from KOS or derived indexing, where terms are taken from the text, with all the problems this brings (see the previous lesson on homonymy, synonymy and polysemy of the natural language).
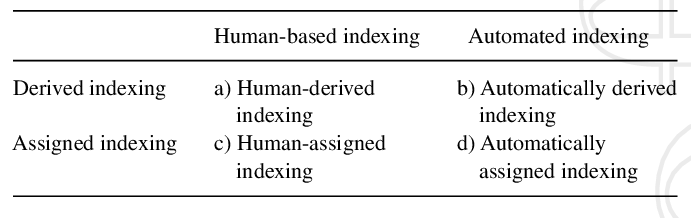
Table showing human versus automated indexing and derived versus assigned indexing (Hjørland 2011).
In computer science, the distinction between different types of indexing languages is rarely made. While a common distinction is between formal ontologies, light ontologies (with concepts connected using general associative relations rather than strict formal ones typical of the former) and taxonomies, the term ontology is often used to refer to several different knowledge organization systems. For example, Grobelnik & Mladenić (2005, p. 279) use the term to refer to hierarchical web directories of search engines and related services and subject headings systems: "Most of the existing ontologies were developed with considerable human efforts. Examples are Yahoo! and DMOZ topic ontologies containing Web pages or MESH ontology of medical terms connected to Medline collection of medical papers". Also, derived indexing may be variously termed, for example, keyword(s) assignment, keyword(s) extraction, or noun phrase extraction (referring to extracting noun phrases specifically).
In related literature, other terms for automatic subject indexing are used. Subject metadata generation is one general example, and the terms text categorization and text classification are common in the machine learning community. Automatic classification denotes the automatic assignment of a class or a category from a pre-existing classification system or taxonomy. However, this phrase may also refer to document clustering, in which groups of similar documents are automatically discovered and named (more about document clustering in lesson 3.1.4).
In this OER, automatic subject indexing is used as the primary term. It denotes non-intellectual, machine-based processes of subject indexing as defined by the library science community: derived and assigned indexing using alphabetical and classification indexing systems for improved information retrieval. While the underlying machine-based principles are somewhat similar, especially when it comes to application to textual documents, the major focus in this OER is on assigned indexing because of the added value provided by indexing systems for information searching, such as increased precision and recall ensuing from natural language control of, e.g., homonymy, synonymy, word form, and advantages for hierarchical browsing (the latter is useful when the end-user does not know which search term to use because of unfamiliarity with their topic or when not looking for a specific item). Further, the term subject indexing assumes applying both alphabetical and classification indexing systems because similar principles apply to automatic processes. However, referring to using the former as subject indexing and the latter as subject classification is common. Finally, while the word automated more directly implies that the process is machine-based, the word automatic is more commonly used in related literature. It is, therefore, in use in this course.
The terminology used to distinguish between different approaches to automatic subject indexing, which will be discussed in lesson 3.1.4, is even less consistent. For instance, Hartigan (1996) writes: "The term cluster analysis is used most commonly to describe the work in this book, but I much prefer the term classification" (p. 2). Or Manning & Schutze (1999, p. 575) explain that "classification or categorization is the task of assigning objects from a universe to two or more classes or categories".
REFERENCES
-
Grobelnik, M., & Mladenić, D. (2005). Simple classification into large topic ontology of web documents. Journal of Computing and Information Technology, 13(4), 279–285.
-
Hartigan, J. A. (1996). Introduction. In P. Arabie, L. Hubert, & G. De Soete (Eds.), Clustering and classification (pp. 1–4). World Scientific.
-
Hjørland, B. (2011). The importance of theories of knowledge: Indexing and information retrieval as an example. Journal of the American Society for Information Science and Technology, 62(1), 72–77.
-
Hjørland, B. (2017). Subject (of documents). Knowledge Organization, 44(1), 55–64. http://www.isko.org/cyclo/subject
-
ISO. (1985). Documentation—Methods for examining documents, determining their subjects, and selecting indexing terms. ISO - International Organization for Standardization. https://www.iso.org/standard/12158.html
-
Manning, C., & Schutze, H. (1999). Foundations of statistical natural language processing. MIT press.