

2.2. Understanding how the platform works
2.2.1. Demonstration of blackboxes
Most of the time, historical newspapers are accessible through digital libraries, such as the NewsEye platform, that provide access to a very large number of documents. Even if, as we have shown, searching on these platforms is easy and fast, these digital libraries rely on often obscure digital processing that affects the way the results are presented. Conducting research in these systems and building relevant and reliable collections is, therefore, a complex task that requires an understanding of how data is indexed and how search tools work.
To fulfil an information need, users, therefore, have to interact with autonomous systems like the search engine of a digital library. They have to express their information need in a way that is compatible with the system. This is not always easy, and the available tools are far from perfect. There is a semantic gap between the way humans understand and process information and the way the machine does. We are not yet able to create the perfect user interface, and we have to use imperfect ones. Unfortunately, this is the best we have so far, and we must learn to understand the biases generated by such interfaces. The main methodological difficulty is to be aware of what is called black boxes.
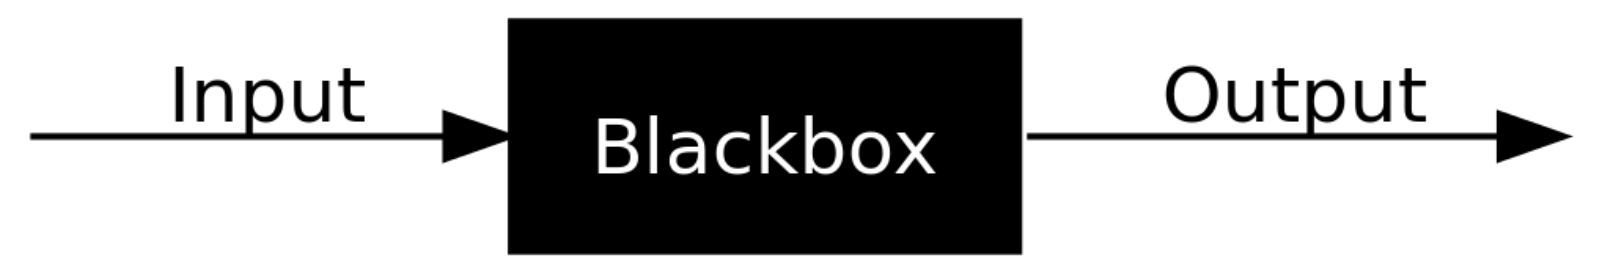
Black boxes describe systems where only the inputs and outputs are known. The internal mechanics are hidden from the user. In the context of a digital library, this can make it difficult to understand why some documents were returned after a query while others were not. There are several aspects of digital libraries that can create such problems.
How is the text extracted?
A lot of documents indexed inside digital libraries are not natively digital. Some transformations need to be operated before a system can ingest them and make them available to search. This is the case with historical newspapers and most historical documents. At first, a document must be scanned to get a digital image that can be processed. However, an image is just pixels without any semantic meaning. It is thus necessary to transform those pixels into characters that can more easily be manipulated by computers. This step is called optical character recognition (OCR). There has been great progress in the creation of algorithms able to do that. However, a lot of historical documents are not of great quality, which will impact the quality of the extracted text. An example of these problems can be seen in the following image.
The result of this process can create imperfect texts that will nonetheless be indexed in the system as is. This can create problems like a query not returning a particular document because the indexed text was not the one actually present in the document.
How are the articles segmented?
Depending on the documents you want to index and what you want to make available for users, it may be necessary to segment them. This is the case for newspapers, for example. After a query, most users would want to find relevant articles. It is, of course, useful to know in which issue certain terms appear, but knowing in which articles of this issue they appear is much more interesting. Segmenting articles from a newspaper is a complex problem that is not yet solved. Thus, the segmentation is not perfect, and it can lead to difficulties in retrieving pertinent articles after a search. This is why the NewsEye platform implements a compound article feature that allows the user to compose an article based on small ones.
How the results are ranked?
After a query in a digital library, the system returns a list of documents deemed relevant. By default, in most systems, those documents are ordered by their estimated relevancy. This relevancy can be computed in different manners depending on how the search engine has been configured. However, this information is often hidden from the users. It is then sometimes difficult to understand why a document has been scored higher than another. Most search systems compute the relevancy of a document towards a query based on three aspects:
-
the frequency of the query terms in the document
-
the frequency of those terms in the entire corpora
-
the length of the document The score of a document will be the highest if the query terms are very frequent in this document but not in the entire collection and if the document is small.
This problem is further developed in section 2.3.2 of this OER.
Platform designers make choices: what do we choose to index?
The number of documents available in a collection can make the process of retrieving information difficult. To access a particular document without the use of an index, there is no other choice than checking every document one by one. This is called a sequential search. As you can imagine, this is not a very efficient method: the more documents there are, the longer the search. To overcome this problem, is is possible to create indexes on various fields of a document. A field corresponds to part of a document (its title, its publication date, its text, etc.). Conceptually, an index associates the value of a field with the location of the document in the system. For example, in a library, it is much more efficient to consult the catalog to know where a particular book is located rather than scanning through all the books until the relevant one is found.
The indexing of metadata is largely covered in the OER7 which is recommended reading, we will concentrate here on the indexing of the text.
If we take the example of the NE platform and its millions of pages, the challenge is met. When indexing a large collection of documents, it is necessary to think about what should effectively be indexed. You have to remember that indexing is a trade-off between disk space/processing power VS speed of search. Thus, indexing too much data can eventually hurt the search capabilities of a system if it is not ready to handle many indexes.
Another thing to think about is the end-users’ needs. It is important to evaluate these needs beforehand so as to not waste processing power on indexes that will never be used. Let’s take as an example the case of the NewsEye project. One of its use case is to be able to highlight individual words in newspapers pages. The pipeline used in this project generates for every page of newspaper a XML file containing information on the position of every word in the page. One would think it is a good idea to index individual words with their position as to ease their retrieval. However, because there are lots of pages and because each page can contain up to 10,000 words, the number of words indexed would easily reach hundreds of millions, even billions. This is not desirable as it would increase the size of an index dramatically, thus slowing the entire system. A solution for this problem is to not index individual words but rather parse the XML file and get the words and their positions when needed (after a particular user query).
The point here is that the designer of a digital library or a search engine has necessarily made technical and methodological choices. From the user's point of view, the choices that have been made may seem negligible. However, they have an impact on the overall functioning of the platform. They may favor certain documents to the detriment of others or classify them in an inappropriate manner.
For all the issues we have discussed here, there is a difference between document availability and document accessibility. Indexing documents in a digital library makes them available to the users. However, they may not all be accessible. A lot of automatic processes can degrade the quality of the indexed documents and the search system itself is not always transparent on how the returned documents were chosen after a user query. Most of the time, users don’t have a say on how a search system is developed. Thus, it is important to be aware of the different biases inherent to digital libraries to take them into account when gathering documents for a corpus.