

2.2. Understanding how the platform works
2.2.3. Opening the blackbox : the ranking problem
As we saw in the previous section, there are many algorithmic steps that have an impact on the results produced by a search engine. Among these steps, the results ranking step is probably one of the most complex and difficult to understand. Fortunately, as explained in OER7, digital library search engines such as the NewsEye platform are often different from commercial search engines. They are often based on classification systems, and they provide full-text search options that allow for fine-tuning of searches.
It is not necessary to understand all the details of these methods, which are reserved for computer scientists. However, knowing the most general principles allows you to be aware of the biases. It can help you develop a more efficient querying strategy, particularly if the data are difficult or impossible to categorize by subject, which is the case of historical newspapers. For example, we will see that the search engine does not necessarily take into account the order of the words in a query. Thus, using the syntax that allows one to search for words in a precise order can be essential.
Let’s define the entities that are concerned with the ranking problem.
- A user (U) has an information need (I).
- He/She wants to identify a set of relevant documents (D) among a collection (C).
- Every document is composed of a list of terms (T).
- The first step for the user is to translate his/her information need into a language that the system can understand, that is, create a query. Such a query is often constituted of a list of keywords that the search system will try to match to the content of documents in the collection.
- True Positive (TP): number of relevant documents returned by the system
- False Positive (FP): number of non-relevant documents returned by the system
- True Negative (TN): number of non-relevant documents not returned by the system
- False Negative (FN): number of relevant documents not returned by the system.
Let's now present some examples of information retrieval models to better understand how a search engine works.
An IR model can mathematically represent the entities at play in an information retrieval task. That is the user need (a query) and how relevant documents are selected and ordered. The first model to have been studied is the most simple: the Boolean Model. In this model, document d is represented as a set of terms ti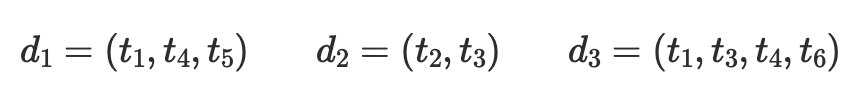
A boolean query can then be expressed using the terms ti and a list of boolean operators: AND (
This model is quite simple but has many drawbacks. First, it is not always easy for users to express boolean queries, which can sometimes be quite complex. Moreover, there is no relevancy order in the resulting documents: either the document matches the query or it does not. The Boolean Model can still be useful in some cases but is still too coarse, especially when dealing with unstructured textual documents such as historical newspapers.
The next model we will study is the Vector Space Model. Its basic idea is to represent documents as a vector of terms in the vector space generated by the list of terms
The weights wi,j can be computed using TF-IDF.
The idea behind TF-IDF is to associate a weight with each term according to its importance in the document. Two aspects are considered to evaluate the importance of a term:
- Term frequency (TF): the more a term appears in a document, the more important it is. There are several ways of computing this (TF computations). The most intuitive one is just to count the number of times a term t,i appear in a document. Other computation methods exist, for example, to normalize this frequency against the length of the document. However, we can’t just take into account term frequency as a measure of the importance of a word because a lot of terms are very common but do not convey much information (articles and pronouns are often quite frequent in every document, for example). One way of alleviating this is to consider how rare a term is in the entire collection; this is the inverse document frequency.
- Inverse document frequency (IDF): in most languages, most of the information is conveyed by words that are quite rare. The IDF measures how rare these words are in a collection, which is equivalent to how much information is conveyed by a term. For example, if the article ‘the’ is very frequent in a particular document (high TF), it is also very frequent in the entire collection (low IDF). Its TF-IDF weight will thus be quite low, which is a good thing because it is indeed not very important. On the contrary, if a term appears in a document but does not appear in any other document of the collection, the IDF will be high. See this page for various ways of computing the IDF.
The final weight is computed by multiplying the TF and the IDF. A query defined by the user will also be represented as a vector in the same vector space. The relevance of every document towards the query can then be computed using a vector similarity function (the most common one being the cosine distance, but others exist).
As you can see, these methods are quite complex and have flaws that can be understood without being a specialist. Most of the time, the user does not know which method is used by the search engine. It is, therefore, important to control as much as possible his search for information by using the means we described in section 2.2. Using precise terms to indicate what you want to obtain allows you to create corpora and datasets that will also be more precise and relevant.